Understand the scores
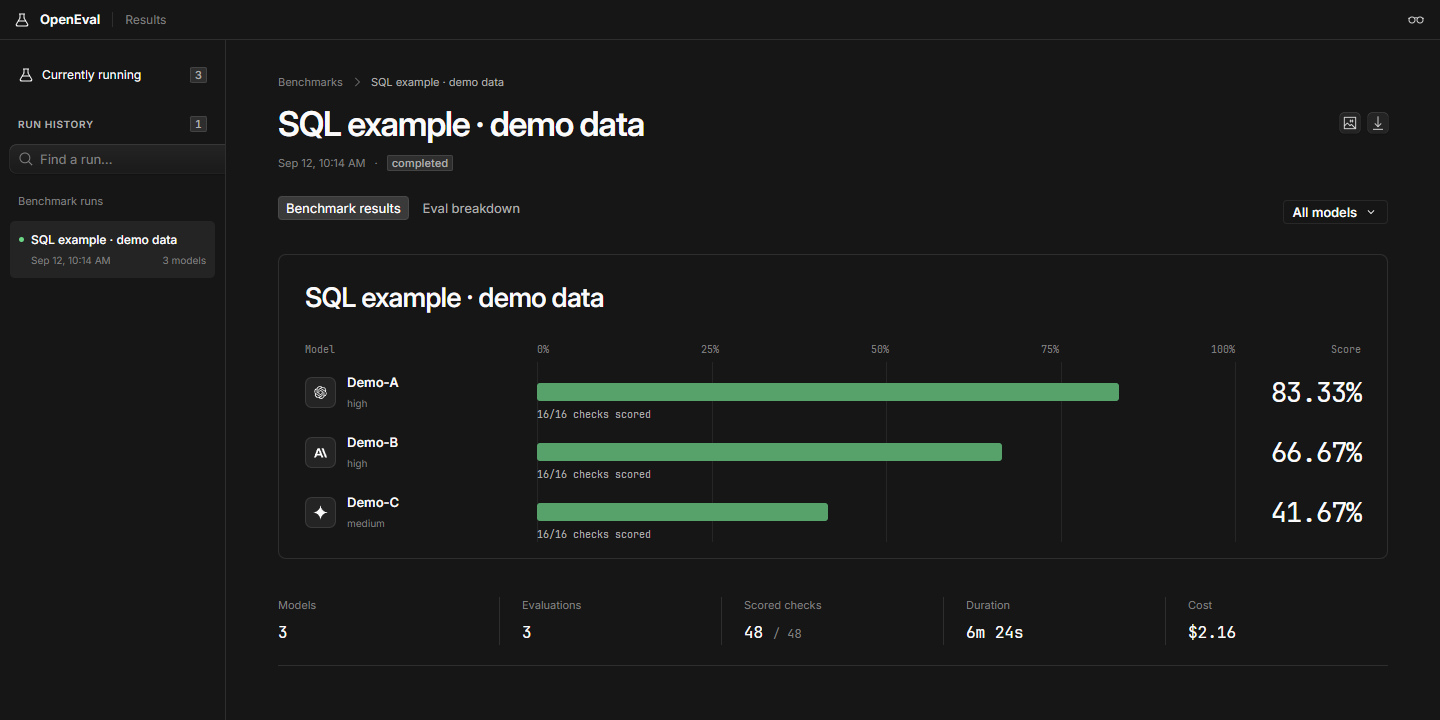
Equal eval weights. Visible unknowns. One final percentage per model.
On this page
Three averages, in order
- Repetitions → criterion
- Criteria → eval
- Evals → benchmark %
aggregation
criterion score = mean(repetition scores)
eval score = mean(criterion scores in this eval)
benchmark score = 100 × mean(eval scores)
An eval with more criteria does not get more benchmark weight. Each eval contributes equally to the final percentage.
Change a decision. See the score.
Score explorerIllustration · one repetition per criterion
SQL queryAsks for dialect
SQL queryBound parameters
Issue summaryActionable summary
Benchmark score75%
Equal eval weights
Select a decision to cycle through pass → fail → unknown. The calculation uses OpenEval's score projection.
Read each number in context
| Viewer value | Interpretation |
|---|---|
| Final percentage | All required criterion scores have known values |
| Checks scored | Criterion scores across evals and repetitions |
| Eval drilldown | Individual criterion scores for one selected eval |
| Runtime | Union of active execution intervals; overlapping work counts once |
| ETA | Estimate for scheduled work using candidate and judge stage timings |
| Cost | Reported candidate and judge spend; ≥ marks a lower bound when some runs have no final cost |